The detector spots basal cell carcinoma.
The trust layer makes the call worth trusting.
SecondLook reads skin-pathology slides for basal cell carcinoma with a detector built on 129,364 labeled tiles. On every confident call it runs a spellcheck - checking where the model looked - so you trust the reads that pass and take a second look at the ones that don't.
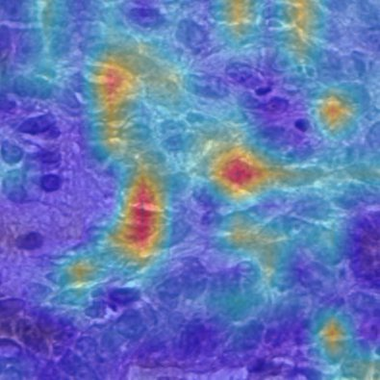
Attention sits on tissue. The check passed and the finding stands.
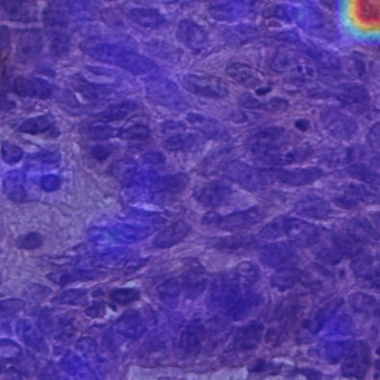
High score, but the heat is on a corner or edge. Routed for human review.
Evidence is unclear, or the check fails closed. No call is made.
The Problem
A model can be confidently wrong.
Two detectors can post the same 1.00 score on the same tile. One read the lesion. The other locked onto a padding corner and never saw it.
The metrics can't tell them apart. The attention map can.
How It Works
A spellcheck for the model's work, never the slide.
On a confident positive, the trust layer reads the score, the attention, and the heatmap - then returns a verdict in plain language. The detector's call never changes; the doctor keeps the final say.
The Evidence, in One Tile
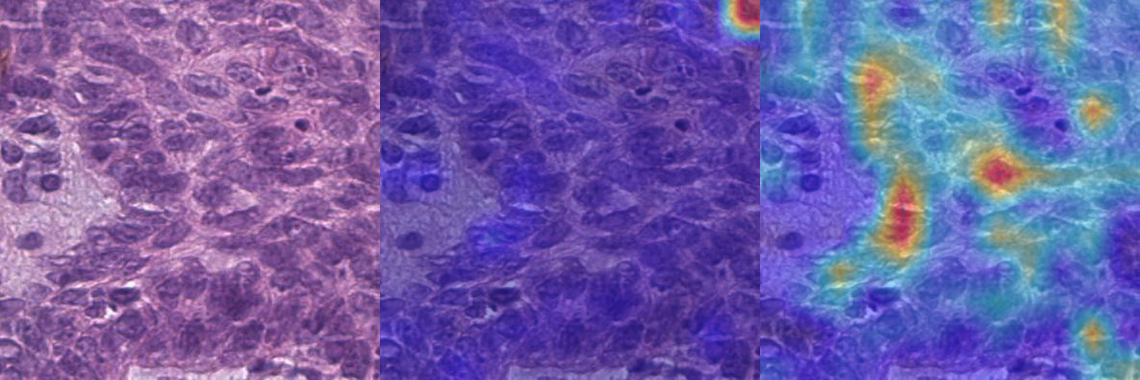
Same tile. Same confidence. Opposite trust.
Two EfficientNet-B4 models, identical but for one training change. Before learned a shortcut and stared at a corner. After reads tissue. Aggregate metrics stay high on both - only the attention map separates them.
Evidence & Standing
Built on a real dataset, shown in the open.
Metrics are tile-level, on an internal held-out split of one dataset (Heidelberg), patient-disjoint.
Run It Yourself
The demo is hosted. The whole thing is open.
Both checkpoints ship in the repo, so you can reproduce the before / after attention without retraining. Claude's check calls the Anthropic API with your own key, kept server-side.
See where it looked.
Open Compare on a positive tile and watch corner heat become FLAGGED and tissue heat become VERIFIED - same detector, different trust.